
Salesforce Implementation Strategies & Designs
Part 1 (of 4): Using Case Types to Support AI.
Introduction
For most of my career, my job has been designing and implementing business process lifecycles in Salesforce. How data moves from source systems to create Cases, Leads, Opportunities and Work Orders for the Field Service Teams. Lately, I have picked up a new component: AI. Not as the subject of the project, but as one more piece I have to design for, the same way I'd design for an integration, an approval process, or data migration.
This series is about that: how an implementation strategist designs for AI inside a Salesforce project, without pretending to be a data scientist. I'm not going to show how a model is trained or how to tune a prompt. I'm going to walk through the actual implementation scenarios using Case Types. I have found that Case Types are one of the most important components to address for setting up the proper foundations for AI.
Are Case Types Mature Enough to Use?
Before you can design a threshold, a branch, or a confidence score, you need to know what you're actually classifying. So, the first question I ask on any of these projects is, are Case Types mature enough to build on?
(Note: You can also use Lead Types, Opportunity Types, Work Order Types etc. Just transfer your object type to this article and it will provide the roadmap for success.)
Here's a real scenario which I recently came across: there are no Case Types. Only one, used for everything. What then with no historical data to reference?
Here's another real one: there are Case Types, but the actual routing is done by tribal knowledge. The email came in from Jane, so Sally and Jake are the only two people who know it's an order — because Jane works in operations, and they happen to know which account she's currently working. Houston, we have a problem.
Some examples are:
"This customer requires special handling." (outlier)
"Don't process this type of order until Finance approves it." (HITL control)
"The documentation says X, but everyone actually does Y.”
In most situations we are missing categories, associated actions, context and definitions that provide a clear mapping from Source to Target record creation.
Historical Data or Not
If there's usable historical data in your Case Types (or Leads, Opportunities, whatever the object is) that’s an excellent start. If there isn’t, as in either Case scenario above, you don't have records to work, map or train from.
You'll need to create the taxonomy and train data before you can design anything on top of it. That's not a technical problem. That's a scope and timeline problem, and it's yours to flag before anyone starts talking about automation.
Taxonomy vs Classification
Before I move on its important to know for this and future articles what the difference is between Taxonomy and Classification and why I mention that creating a taxonomy is a key part of this process.
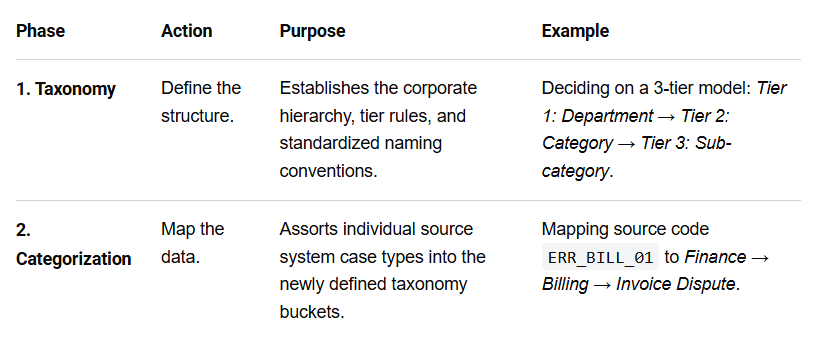
Classification assigns an item (ie. Case support ticket) to a specific, functional group or queue based on pre-defined operational criteria like a operational bucket or routing rule. (e.g., "Billing Dispute" or "Priority 1 Incident"). A classification (or categorization) is the active process of sorting individual items into predefined categories or in our case groups based on shared traits using flat or loose groupings whereas…
Taxonomy is the overarching framework or hierarchical structure that defines categories and their relationships. Taxonomy builds the entire hierarchical framework of relationships and parent-child categories that define what the case types actually are. It’s a deeper, organized system that builds a parent-child or tree-like hierarchy. It maps out primary categories, subcategories, and granular case types (e.g., Billing > Invoice Error > Duplicate Charge). So the ‘Duplicate Charge’ category will define what path it takes for resolution. I run through the process later. You can start with a flat taxonomy and begin to build to the levels from there.
Rule: While all taxonomy is categorization, not all categorization is taxonomy.
Create an Action: This path can be a Salesforce flow that triggers an action like routing a record to a queue or User, send an alert or notification, create follow up tasks or call an Apex Action or External Service (such as notifying a third-party billing platform via API). In many cases it will involve multiple items.
"Trust but Verify"
Let's talk about “trust but verify” in an AI-assisted business process. Notice I say assisted, not new but assisted or supportive. You're typically not overhauling a primary process that already involves source-to-target systems integrations, Service Cloud, CPQ, and so on. You're identifying where, inside an existing process, AI creates ROI you can prove.
When teams are asked to “improve a process, with AI” it can be approached as a redesign (what steps can be removed, merged or automated) rather than just “find the part of the process step to insert AI.” If you just start swapping out process steps for AI there will be missed opportunities for ROI. Data must also be trusted and I do a tremendous amount of work on the source systems and integrations to make sure the data is delivered in a way that the target system can consume and act on.
You don't have a year to prove that ROI. You may have a quarter, if you're lucky. That's your runway. An MVP that produces real metrics - proof that additional resources, finances, and timeline can be justified - is what gets you to the next phase. Providing quick wins and additional value adds provides more support for your next MVPs. The more preparation you do up front, the more grace you get when you hit the speed bumps and don't forget the startup costs and timeline - in dollars - that always surprises everyone.
"Milestones and Measures"
So how do you get from “trust” to actually verifying the system works? Set up Milestones and Measures.
Milestones - the kind you'd configure through an Entitlement Process in Salesforce - show you where the blockers are, where a Case or Opportunity is missing its timeline expectations, and gives you a place to build accountability into the status itself. For measure, think in terms of “how many Cases get re-classified?” or “are X SLAs being met?” The key takeaway here is to start with questions, not dashboards.
Milestones and Measures also keep people from gaming the system because any change comes with pushback, a detail worth flagging for any CoE or adoption conversation. If you are curious of what I am referring to, google the phenomenon called the Cobra Effect which describes when an attempted solution to a problem makes that problem worse. The history of the Cobra Effect is also a great read.
One implementation note here: when a client says “I want an alarm or my teams need an alarm when X happens,” what they usually need is a filter. A way to see the data early enough with enough clarity to take the right action before the alarm would ever fire. Rework the situation and see if you can’t find a better solution through automation or other process.
Over time, the system gets better with daily and weekly iterations: the client adds values, tweaks existing ones, brings in better data from source systems for better threshold insight, and works on the data as a company ‘asset’ that usually needs attention anyway: IoT data on assets, SAP source alignment, metadata management. All standard implementation work. AI doesn't replace it; it depends on it.
The Use Case
Choosing the right Use Cases is an important first step for your AI journey. Some interesting use cases I’ve run across are: Insurance Claims Triaging, Loan or Credit Approvals, or Support Ticket Resolution. The first two are high-stakes and heavily regulated so I would only approach them if the client is mature in AI experience and readiness. The support ticket use case is one I've seen too many times, and it's simple enough to be less useful as a teaching example. The Case to Quote/Invoice use case sits in the middle and can apply to many industries – enough complexity to be interesting, simple enough to actually walk through in a few articles.
A case to quote workflow: a case record comes in, the system classifies it, scores its own confidence in that classification, and either drafts a quote automatically or routes the case to a human with the client always getting a final YES/NO on whatever quote reaches them. A threshold is the driver that applies rules to the action of submitting to the client or to a human for validation.
The quote or invoice pulls and aggregates data from the warranty (manufacturer and service provider) on what is covered for parts and services, what is the customers cost, a break down of payments according to their financial template. There is also a scheduling engine that runs options for when the customer chooses to move forward by providing dates and times for service techs to begin the work.
Contract and Vendor RFP Response Drafting is another one I'll cover later. It's a strong ROI use case for content generation rather than pricing, and it's sustainable across a lot of divisions. In short: The workflow is for a proposal team response to a client RFPs. The inputs are a 40-page RFP document and a scattered email thread of internal answers. The recurring task: turn that into a structured list of answerable requirements.
Choose your Use Cases carefully and walk through them with some diligence as this will effect the project tremendously.
The design question underneath all of these use cases is the same: “Why did the system decide this?”
That question is why you'll need metrics, not vibes or assumptions. Regulatory and audit requirements like fair lending laws, for example apply directly to the high-stakes use cases, and every other use case still needs its own version of “how do we know we're succeeding, and what's the gap if we're not?” Some of this classification can be handled by fixed rules; the higher-stakes cases need more. More values, policy rules, and often complex regional policies overlay sitting on top of the base rules.
Past that layer is where a generative system can produce a quote draft, an explanation, or a piece of correspondence and where things can go off the rails if you haven't done the groundwork. I'm not saying that to be dramatic. I'm saying: put a number on it, know how you'll hit that number, and set expectations by doing the prep work first; Case Types, source data and access, historical data, metadata, reporting, page layouts. Do your homework before you promise anything. It's extra work you might not get separately billed for, but it buys you Clarity.
Clarity
A quick note on Clarity. Clarity is what you want. Clarity promotes Calm. Calm provides Focus. Focus drives Confidence. If you're the lead on one of these projects, people are measuring your confidence every day, whether they say so or not. Doing the groundwork above is how you earn it honestly instead of faking it. These are projects that can get under you real quickly. I have the solution for you and its in the Part 2 for Preparation.
The Vocabulary You Actually Need
Here's the handful of terms in the design:
Terms Sheet:
Deterministic or Structured: deterministic means the same input always produces the same output, and you can point to exactly which rule fired. This is why it is coupled with Structured data.
Probabilistic or Unstructured: Probabilistic means the output reflects likelihood, and the same input can produce different outputs across runs. This is why it works with unstructured data sets like email and chat or voice. As mentioned, there may also be multiple asks in one email pertaining to an issue with an asset and another invoice with an invoice.
Threshold: the cutoff value that determines which path a case takes: straight-through to the customer, or to a human. It can be static, or it can move as you get more data.
Confidence vs. Correctness: these get conflated constantly, so it's worth being precise.
Confidence is a probabilistic estimate of how certain the system is.
Correctness is a fact: for a given quote and a given, fixed version of the policy rules, the YES/NO either matches the rule-based outcome or it doesn't. There's no “60% correct,” the same way there's no “60% pregnant.”
Where probability actually creeps in is at the edges; rule ambiguity (the policy language itself is vague, so reviewers disagree) or measurement noise (your human labelers make mistakes too). Neither of those makes correctness itself fuzzy; it means your ‘ground truth’ needs its own adjudication process.
False Positive / False Negative: a false positive here is an auto-approved quote that shouldn't have gone through. A false negative is a good quote that got routed to a human unnecessarily. Your threshold is a tradeoff between these two costs, not a “right answer” you calculate once and forget.
Human-in-the-loop (HITL): the workflow pattern where a human reviews, approves, or overrides the system's output before it's final. This is your YES/NO click, and it's the deterministic check that re-enters the process on the other side of the generative layer.
Escalation path: the defined route a case takes when it doesn't meet the automated criteria. This is your human checkpoint, and it needs to be a real, designed path and not a fallback nobody built.
That's the working vocabulary. Everything else; Model vs. Agent, Temperature, Grounding, Hallucination, and the rest is useful to know, but it belongs to the people building the generative layer, not to the person designing where it fits in the implementation. I’ll cover these later in future articles once we establish the grounded truth.
Coming in Part 2 >>>
Applying the Case Types, preparation, multiple source systems, project experiences, processes and more.